Staircase Policy
S-WAM · Staircase World-Action Model

Staircase Policy

Streaming Inference for World-Action Models with Large Action Chunks

Guoheng Sun1 Chen Chen2 Jin Wang3 Ang Li1 Teresa Lv2,*
1University of Maryland, College Park 2Independent Researcher 3Oxford Robotics Institute, University of Oxford
*Corresponding author
50 executed actions
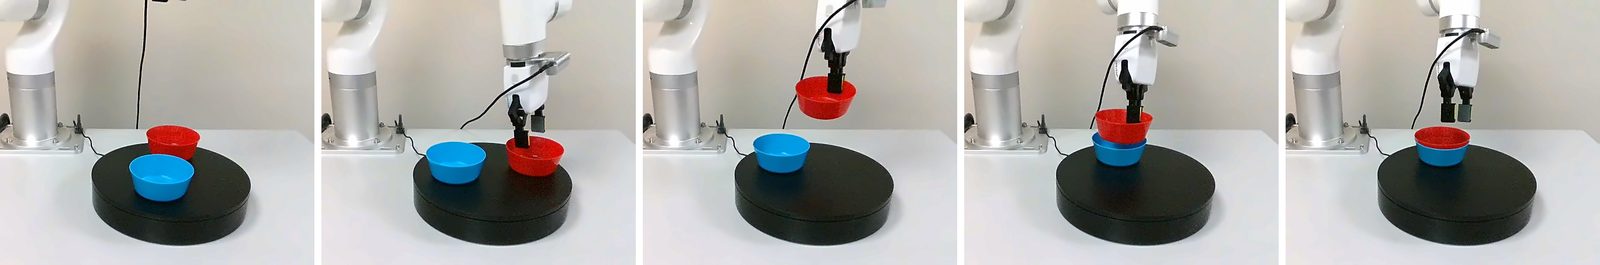
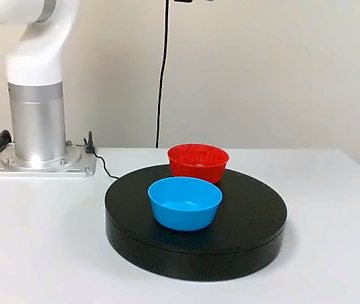
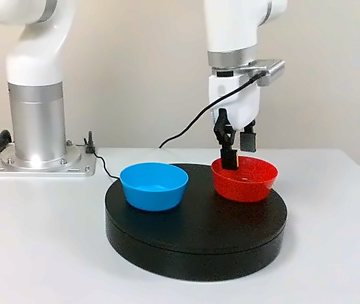
Camera view of the stack-bowl (dynamic) task: the arm picks the red bowl and stacks it on the blue bowl on the turntable. camera now · o0
plan: o1
Actions conditioned ono0
Actions since that frame0
VLM backbone 0
Future predictor 0
Action expert 0
Five sub-chunks of ten actions. Dots count expert passes; dashed outlines are the optimal actions.expert at τ = –
action 1executed 0 / 50action 50
The backbone reads o0 and the instruction once for the whole chunk.
0backbone passes
0expert passes
–expert passes before the first action
–longest run on one frame
Schematic of Algorithm 1 with K=5, G=10 and a fixed commitment of all five sub-chunks (the error-gated early replan is not shown). Per 50 executed actions, S-WAM and vanilla at Hexec=50 both spend one backbone pass and five expert passes, the paper's compute-matched setting, and S-WAM also re-runs the millisecond-scale future predictor at each boundary. Vanilla at Hexec=10 executes 10 actions per query before replanning: five backbone passes and 25 expert passes per 50 actions. Bar heights are illustrative.
97.7%success on LIBERO
87.9%success on LIBERO-Plus
3.62×throughput of conventional execution at comparable accuracy
73.3 mstime to first action, down from 123.6 ms
Videos
Video 1 of 3

Same scene, three policies

2:07

Nine tasks in two chapters, static then dynamic. Each segment puts S-WAM next to vanilla chunking at Hexec=20 and 50 on the same task, shown from the third-person and wrist cameras. The timer shows real seconds and stops when the task is completed.
Video 2 of 3

S-WAM across tasks and layouts

1:44

S-WAM alone. An overview with one trial per task, then successful trials on each of the nine tasks, every tile a different object layout.

Video 3 of 3

Failure modes

0:52

Where each policy fails: vanilla at Hexec=20 is too slow to follow moving objects, vanilla at Hexec=50 is imprecise, and S-WAM has occasional failures of its own.

Abstract

World-Action Models (WAMs) improve robotic manipulation by conditioning action generation on predicted future observations, but future prediction adds further inference overhead to already expensive iterative action generation. Action chunking can amortize this cost over multiple actions, yet performance degrades over long execution horizons because later actions remain conditioned on stale observations.

We introduce Staircase Policy, a streaming inference and training framework that turns a flow-matching VLA into a JEPA-style WAM and partitions a large action chunk into sub-chunks at staggered denoising stages. Near-term actions are executed as soon as they become available, while later actions continue to be refined. At each sub-chunk boundary, the future latent is re-predicted from the latest observation and used to update all unexecuted actions, enabling long-horizon execution without repeated full policy inference. The resulting future-prediction error can further serve as a signal for adaptive chunking.

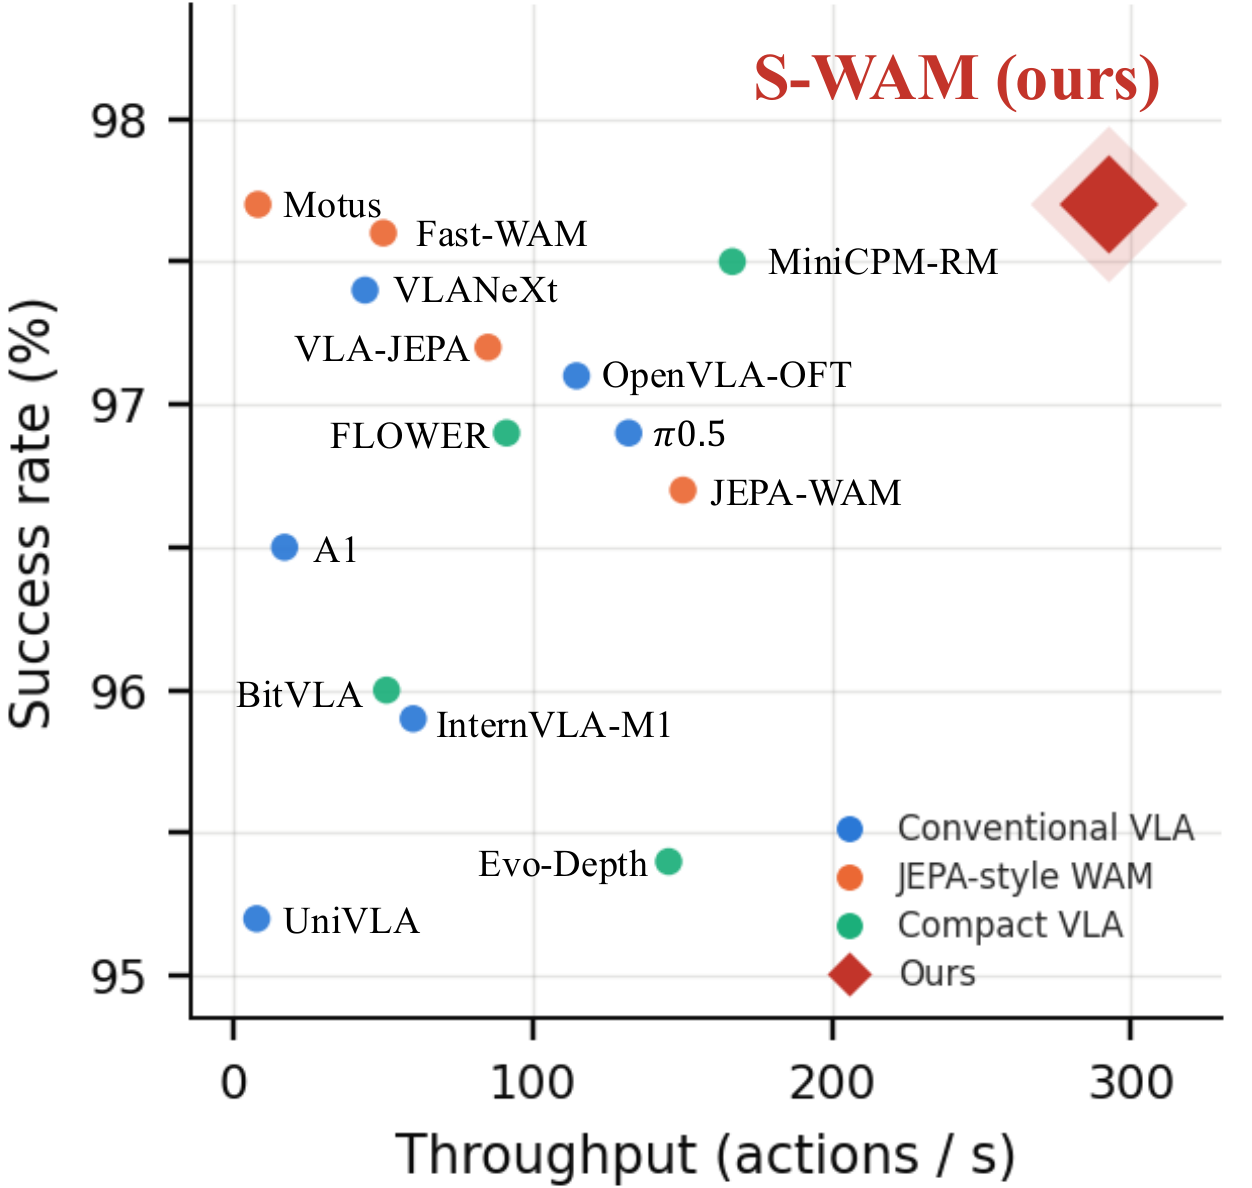
S-WAM achieves 97.7% on LIBERO and 87.9% on LIBERO-Plus, and improves performance across multiple policy backbones and real-robot tasks. It reaches 292.7 executed actions per second, 3.62× the throughput of conventional execution at comparable accuracy, while reducing time-to-first-action from 123.6 to 73.3 ms. With additional inference optimizations, throughput further increases to 642.9 actions per second.

Success rate versus measured inference throughput on LIBERO.

Success rate versus measured inference throughput on LIBERO. Existing methods show a clear speed–accuracy trade-off: policies with higher success often rely on shorter replanning intervals and larger backbones, while faster policies achieve lower success. S-WAM reaches 97.7% at 292.7 executed actions per second, matching the highest success rate at 1.8× the throughput of the next-fastest method shown. Success rates come from the original papers; every throughput is measured from released checkpoints under one protocol.

Method

Execute the near actions now. Keep refining the far ones.

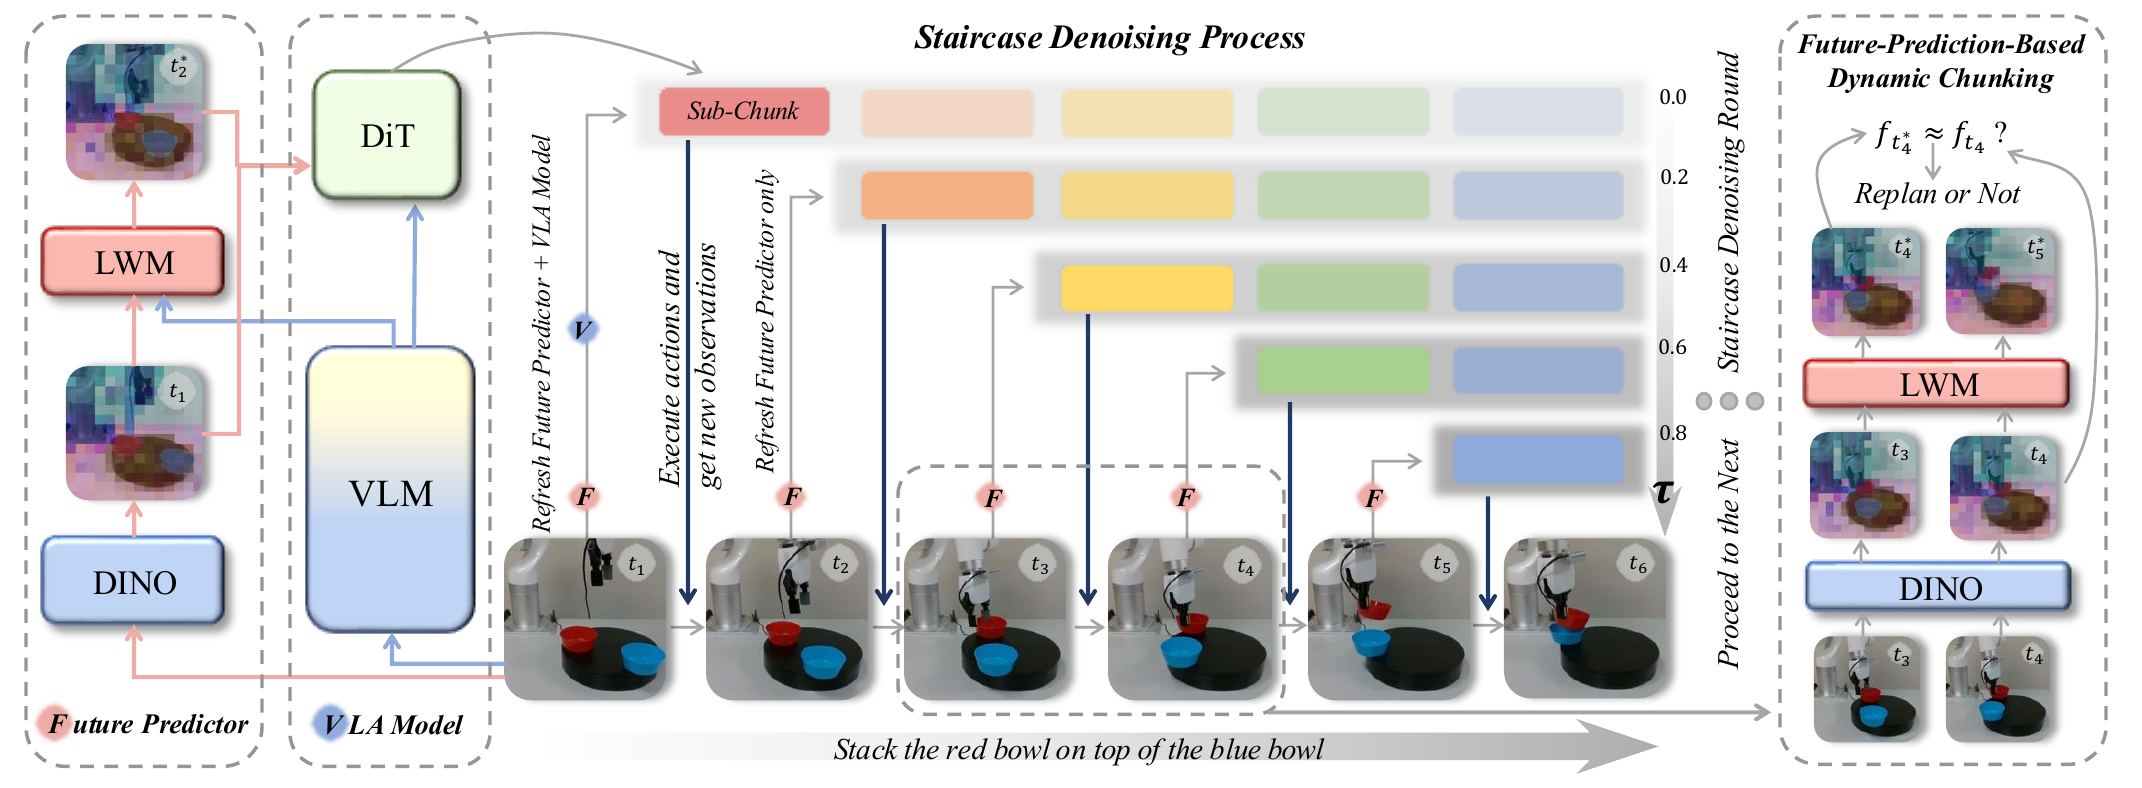
Staircase Policy adds a lightweight future predictor to a flow-matching VLA: a frozen vision encoder gives h = E(o), and a decoder g predicts the feature map of a near-future observation. The action expert is conditioned on the current observation, the predicted future latent, and the cached semantic context. Two properties of long-horizon action generation shape the design.

Denoising needs vary across the horizon

Near-term actions are easier to predict than distant ones, and flow-matching trajectories are nearly straight, so one velocity evaluation already points toward the data. The chunk is split into K sub-chunks of size G (H=KG; we use H=50, K=5, G=10). The first sub-chunk is read out after one denoising step and each later one gets one step more. Every buffer position stays at the same flow time τ, so the expert always sees the shared-τ inputs it was trained on.

Visual conditioning should be refreshed

Object poses, contacts and robot configuration change during execution, while the instruction and high-level semantics remain largely unchanged within a chunk. At each sub-chunk boundary only the lightweight future predictor is re-run on the new observation; the vision-language context is reused. The backbone runs once per chunk and the predictor once per boundary at millisecond-scale cost. The refreshed condition updates every unexecuted action without a full replan.

Overview of Staircase Policy.
Overview of Staircase Policy. ti denotes a time step and ti* the predicted future.

Training under the deployment schedule

Standard training never exposes the policy to partially denoised buffers, one-step readouts, mid-chunk changes in conditioning, or self-predicted future latents. We therefore train under the same streaming schedule used at deployment and supervise the readout the controller actually consumes rather than the velocity. This also converges considerably faster than conventional chunk training.

Future-prediction error as a chunking signal

Because the refresh runs as a chain, every boundary yields a prediction–realization pair that a policy denoising the chunk only once never has. The discrepancy grows when the scene departs from what the model anticipated, so thresholding it makes the executed horizon depend on the data instead of being fixed at K sub-chunks.

Real robot

Nine tasks on an xArm 850, running onboard a Jetson Thor

Thirty teleoperated demonstrations per task were collected with a Meta Quest 3, and each task is evaluated over 40 trials. Six tasks are static and dynamic versions of three skills. In the dynamic versions the objects ride a turntable that turns continuously at 22.5°/s, so the target keeps moving while the robot acts. The other three tasks cover sustained, precise and multi-stage manipulation. Pick a task to watch S-WAM and both vanilla baselines side by side, from the third-person and wrist cameras, next to the task's success rates over all 40 trials.

S-WAM
Third-person
Wrist
Vanilla, Hexec=20
Third-person
Wrist
Vanilla, Hexec=50
Third-person
Wrist
Success rate on this task (%), 40 trials
Vanilla, Hexec=20 Vanilla, Hexec=50 S-WAM
Averages across tasks (%)
Vanilla 20Vanilla 50S-WAM
6 static67.557.172.5
3 dynamic10.825.844.2
All 948.646.763.1
One teleoperated training demonstration
Five frames of the selected demonstration.

The clips are the single trials shown in the first video, played back with the real elapsed time on the timer. The success rates come from all 40 trials. On static tasks, vanilla execution loses ground when it commits to 50 actions (57.1 against 67.5 at Hexec=20). The dynamic tasks expose both vanilla regimes. Frequent replanning is hurt by inference latency while the turntable keeps moving, giving only 10.8. Executing 50 actions per query helps (25.8), but the later actions drift over the long horizon. S-WAM updates its unexecuted actions from new observations and reaches 44.2. Vanilla at Hexec=50 is compute-matched with S-WAM; at Hexec=20 it replans 2.5× as often.

Results

Fast enough for large chunks, accurate enough to trust them

We evaluate on LIBERO (four suites of ten tasks), LIBERO-Plus (seven perturbation categories over the same tasks) and DOMINO (dynamic manipulation with scene changes during execution). Unless stated otherwise the base policy is a 2.3B latent World-Action Model. Within each backbone, S-WAM and the vanilla baseline share data, initialization and training configuration. For every 50 executed actions, S-WAM with K=5 and vanilla execution at Hexec=50 both need five denoiser passes and one backbone pass, so Hexec=50 is the compute-matched baseline and Hexec=10 the conventional short-horizon one.

Inference speed on the LaWAM host

Policy
Executed actions / s ↑
Time to first action, ms ↓
LIBERO SR

Measured at batch 1 on the same device. CUDA Graph captures the geometry and denoising calls to cut launch overhead; prompt cache reuses the frame-invariant prompt computation. Neither changes the actions produced, so the success rate is unchanged. Against vanilla at the horizon that matches its accuracy (Hexec=10), S-WAM raises throughput 3.62× and cuts time to first action by 40.7%.

Full optimization ladder
MethodAction/s ↑SpeedupTTFA (ms) ↓
Vanilla (Hexec=10), eager80.9 ± 1.01.00×123.6
Vanilla (Hexec=50), eager402.5 ± 6.84.98×124.2
Ours (Hexec=50), eager292.7 ± 9.43.62×73.3
+ geo & DiT CUDA Graph625.7 ± 16.17.73×53.2
+ prompt cache642.9 ± 18.27.95×48.6

Robustness on LIBERO-Plus

Success rate (%) across seven perturbation dimensions. S-WAM has the best average, 87.9%, 17.3 points above the compute-matched vanilla baseline. Robot initial-state perturbation is where that baseline is weakest (49.7); S-WAM reaches 76.0 there, the best score in the table, consistent with the benefit coming from re-observing scene geometry during execution.

MethodBackgroundRobotCameraLanguageNoiseLayoutLightAvg.
ST-WAM74.260.155.479.379.574.393.073.7
DreamWAM71.563.653.794.867.180.796.675.4
VLA-JEPA93.667.163.385.466.385.195.679.5
ROCKET-VLA91.841.891.878.092.581.294.781.7
VLANeXt82.565.790.481.894.180.895.984.5
WorldPilot96.460.682.887.293.680.598.685.7
InternVLA-A1.598.255.183.186.995.685.296.485.8
Vanilla, Hexec=5083.049.777.153.980.064.885.770.6
Vanilla, Hexec=1095.273.491.577.794.382.196.087.2
S-WAM (ours), Hexec=5096.676.089.585.290.479.398.687.9

Training efficiency

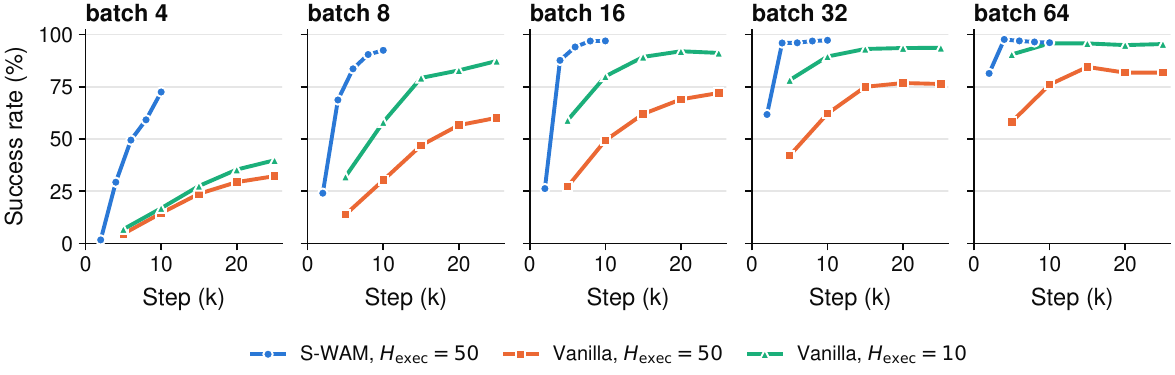
Success rate versus training steps across five global batch sizes.

Training under the streaming schedule costs more per step but converges much faster. At batch size 4, S-WAM reaches 72.5 success after 10k steps, against 32.2 for vanilla even after 25k steps; the gap narrows to 14.3 points at batch size 64. Each streaming step costs 1.87× more FLOPs, yet S-WAM ends at a higher success rate while spending fewer total training FLOPs.

Analysis

Where the gains come from

Execution length and the speed–accuracy trade-off

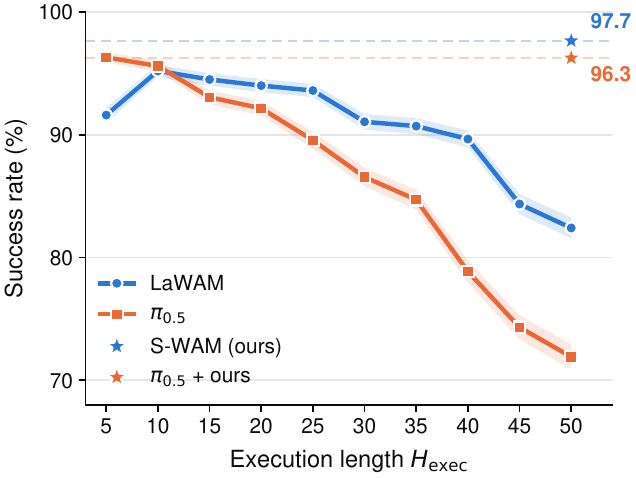
Executing more actions per inference hurts conventional policies. With only Hexec varied, our backbone drops from 95.2 at Hexec=10 to 82.4 at 50, and π0.5 drops from 93.2 to 66.4. S-WAM executes the full 50-action chunk and still reaches 97.7 and 96.5 on the two backbones, above the best vanilla result on either. The limitation lies in executing later actions under stale conditioning, not in the chunk length itself.

Success rate versus execution horizon, averaged over four suites.
Success rate versus execution horizon, averaged over four LIBERO suites. Vanilla peaks at or near Hexec=10 on both backbones.

Choice of denoising steps and sub-chunk size

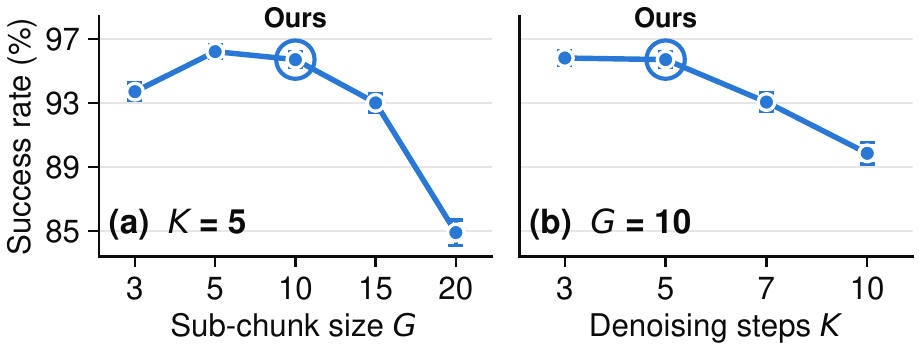
Effect of chunking hyper-parameters.
Effect of the chunking hyper-parameters, where H = K × G.

The chunk length is set by the number of denoising steps K and the sub-chunk size G; increasing either lengthens the executed horizon and raises throughput. Performance stays stable over a broad range and degrades only when the chunk becomes too long for the available denoising steps. All experiments use K=5 and G=10 unless stated otherwise.

Small models vs. execution-level acceleration

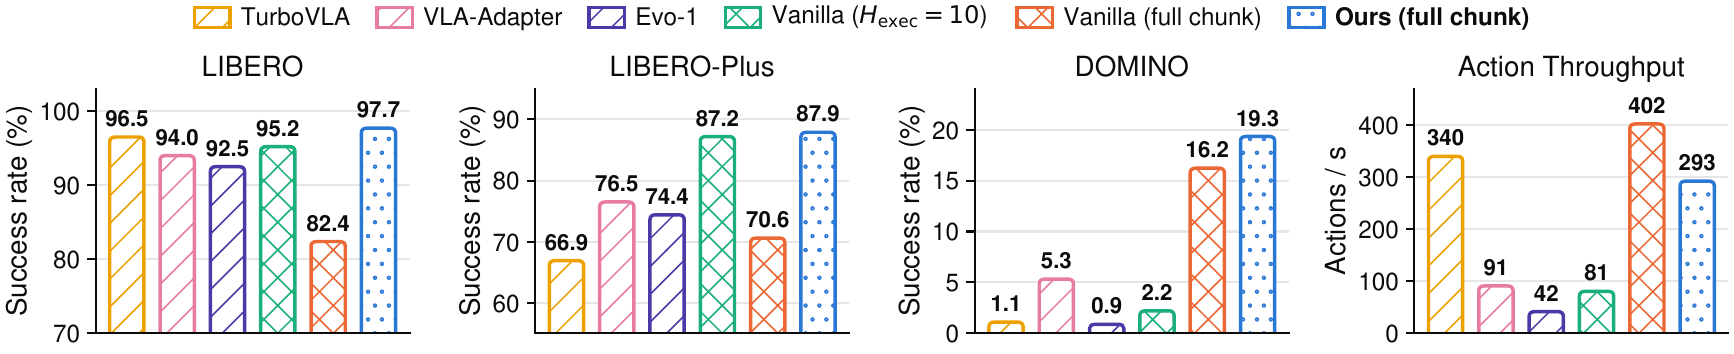
Comparison with compact VLA models on LIBERO, LIBERO-Plus and DOMINO.
Comparison with compact VLA models on LIBERO, LIBERO-Plus and DOMINO, plus action throughput.

TurboVLA (0.2B), VLA-Adapter (0.6B) and Evo-1 (0.77B) are strong on LIBERO, but the gap widens on harder benchmarks: 66.9–76.5% on LIBERO-Plus against 87.9% for S-WAM, and 0.9–5.3% on DOMINO against 19.3%. Shrinking the model works well in easier settings; execution-level acceleration keeps the capacity of a larger policy. The two paths are complementary.

Future-prediction error as an adaptive-chunking signal

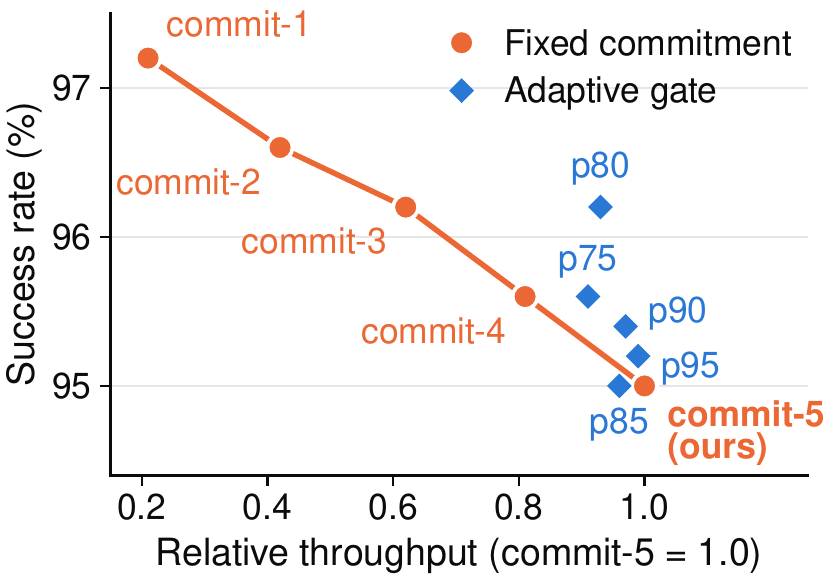
Commit-X always executes exactly X sub-chunks before replanning. pX sets the gating threshold to the X-th percentile of the future-prediction error on the validation set, replans when the error exceeds it, and commits to at least four sub-chunks. Adaptive chunking adds an operating point between commit-4 and commit-5: p80 reaches 96.2 success with only a modest further drop in throughput.

Success rate against throughput for fixed and adaptive commitment on LIBERO-Long.

Transferability across policy backbones

S-WAM transfers across backbones. Each backbone keeps its own training configuration; the schedule, objectives and method hyper-parameters are unchanged. Act/s is executed actions per second; TTFA is time to first action (ms). π0.5 and FLOWER were not pretrained to predict future latents.

BackbonePolicySpatialObjectGoalLongAvg.Act/s ↑TTFA ↓
LaWAM (2.3B)S-WAM98.6100.097.095.097.65292.773.3
Vanilla, Hexec=1096.298.495.690.695.2080.9123.6
Vanilla, Hexec=5087.280.688.073.882.40402.5124.2
π0.5 (3.5B)S-WAM98.098.695.294.296.50243.280.6
Vanilla, Hexec=1094.699.091.687.493.1575.7132.2
Vanilla, Hexec=5066.467.672.858.666.35378.3134.8
FLOWER (1.0B)S-WAM97.499.698.688.896.10234.372.7
Vanilla, Hexec=1098.899.296.689.696.0585.5117.0
Vanilla, Hexec=5085.685.090.667.082.05416.0120.2

Against vanilla execution at Hexec=50, S-WAM improves success by 15.25, 30.15 and 14.05 points on LaWAM, π0.5 and FLOWER. On all three backbones it matches or beats vanilla at Hexec=10 while raising throughput 2.74–3.62× and cutting time to first action by 37.9–40.7%.

BibTeX
@misc{sun2026staircasepolicystreaminginference,
      title={Staircase Policy: Streaming Inference for World-Action Models with Large Action Chunks}, 
      author={Guoheng Sun and Chen Chen and Jin Wang and Ang Li and Teresa Lv},
      year={2026},
      eprint={2609.36471},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2609.36471}, 
}